

Add a Custom Prompt
Prerequisites
Integrate a pre-built or custom LLM before creating a prompt. See LLM Integration.Steps
- Go to Generative AI Tools > Prompts Library.
- Click + New Prompt (top right).
-
Enter the Prompt Name, then select the Feature and Model.

-
The Configuration section (endpoint URL, auth, headers) is auto-populated from the model integration and is read-only.

-
In the Request section, create a prompt or import an existing one.

-
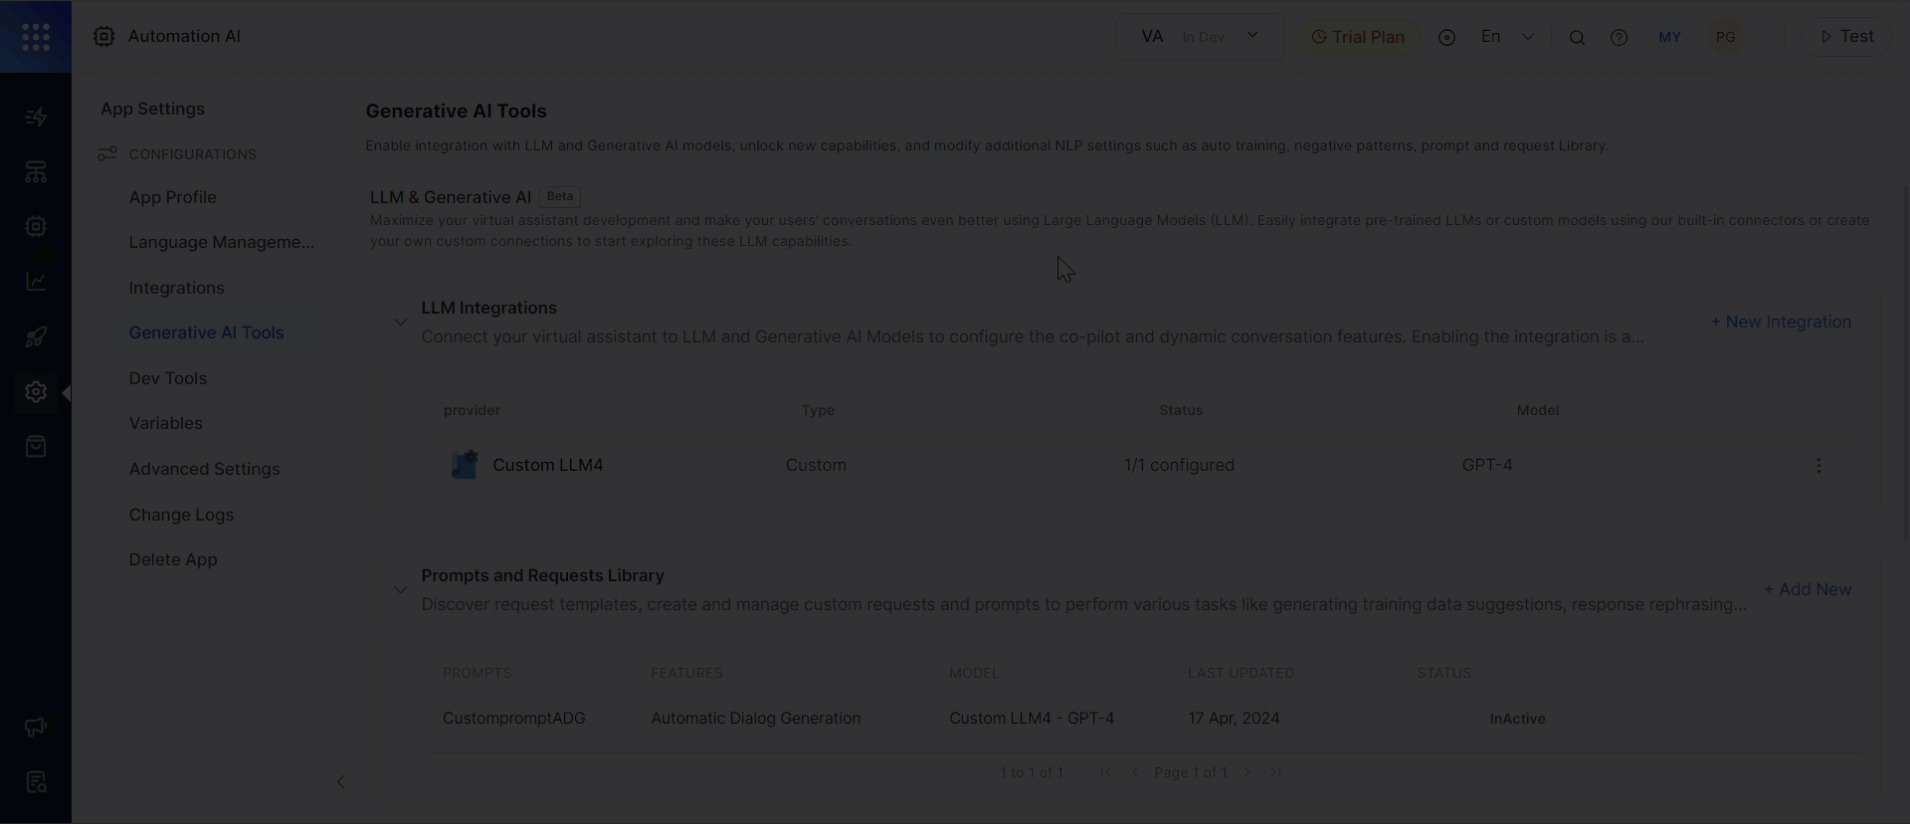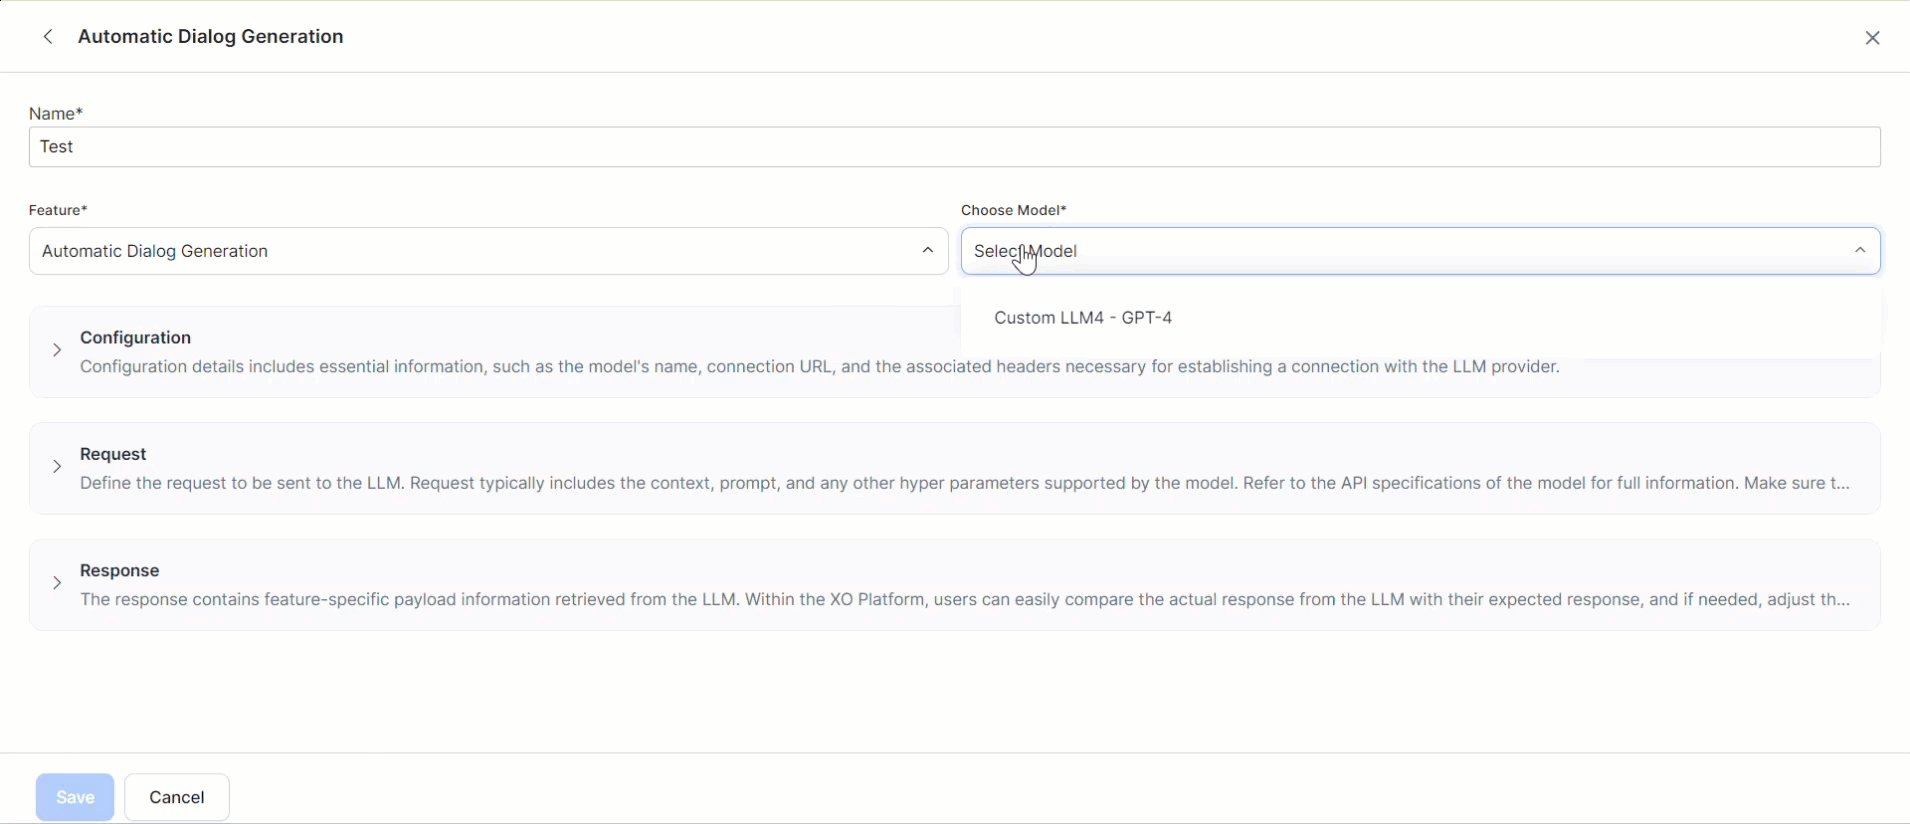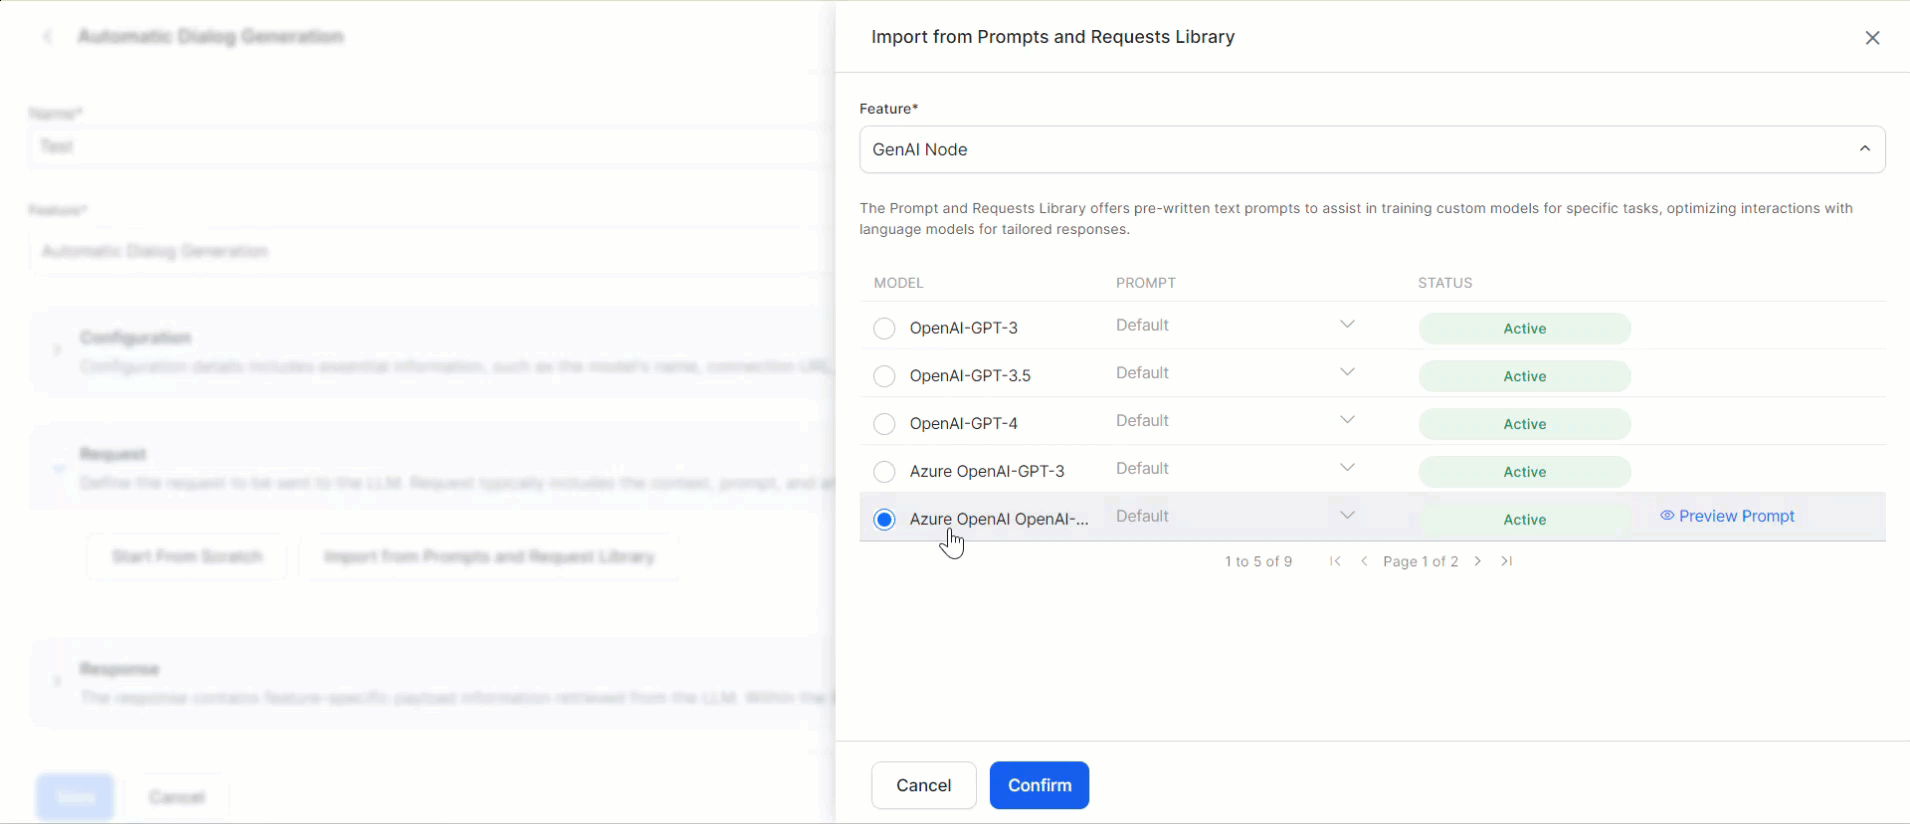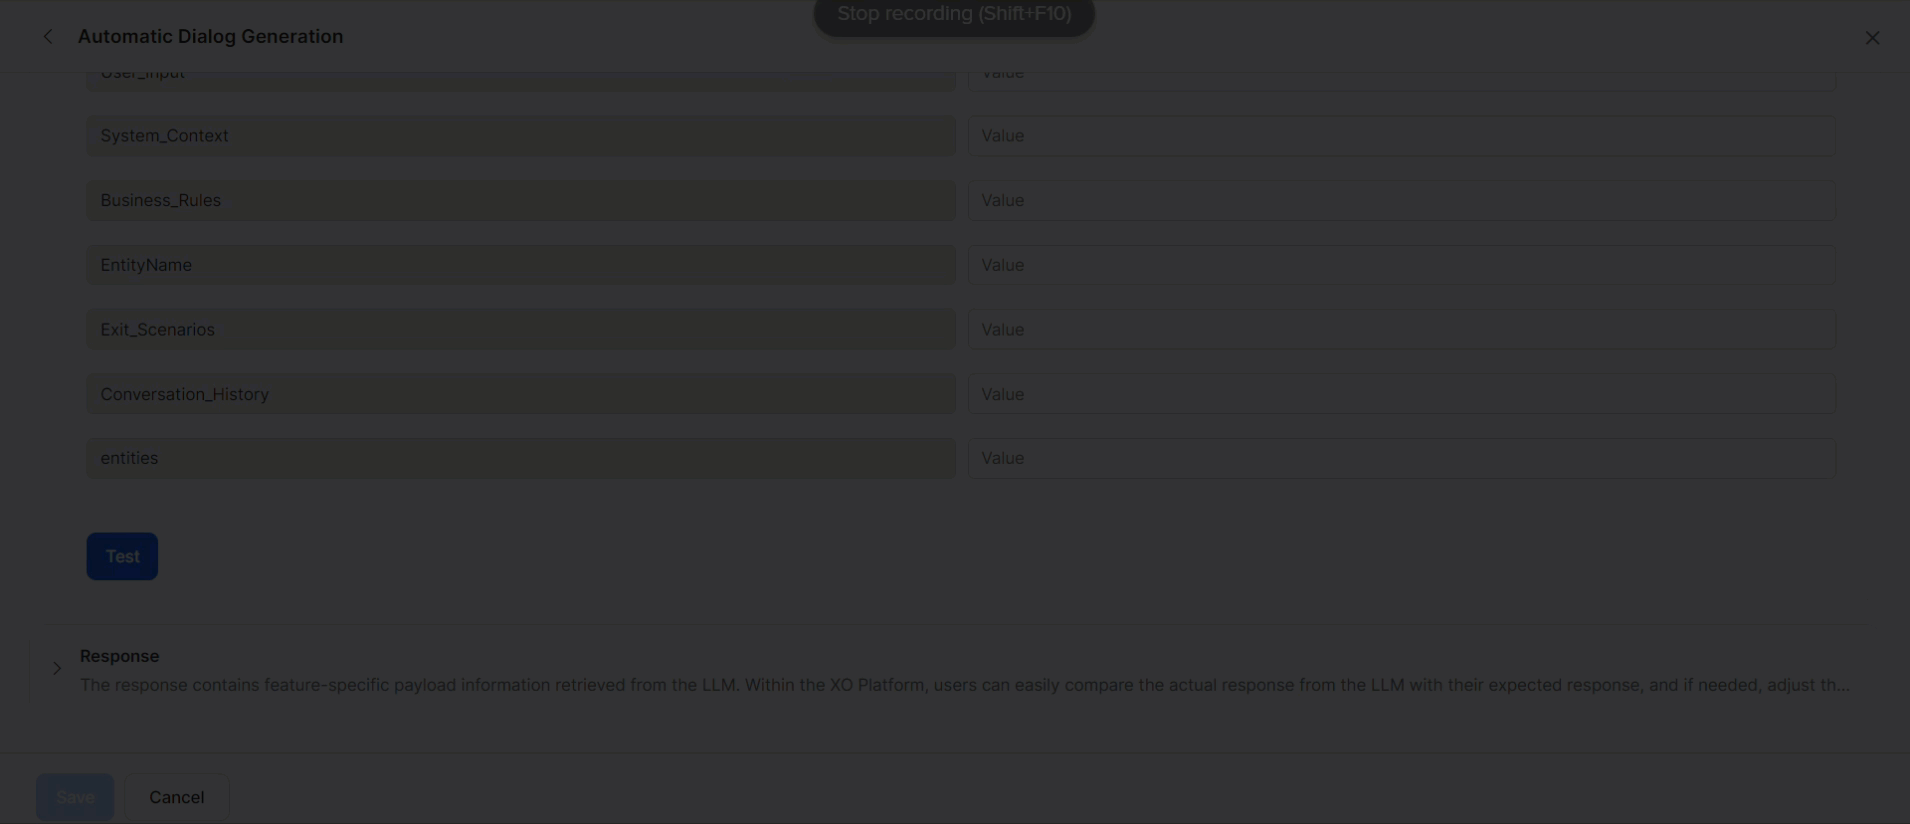
Click Import from Prompts and Requests Library.
-
Select the Feature, Model, and Prompt. Hover and click Preview Prompt to review before importing.
You can interchange prompts between features.
- Click Confirm to import the prompt into the JSON body.

-
Click Import from Prompts and Requests Library.
-
(Optional) Toggle Stream Response to enable streaming. Responses are sent incrementally in real time instead of waiting for the full response.
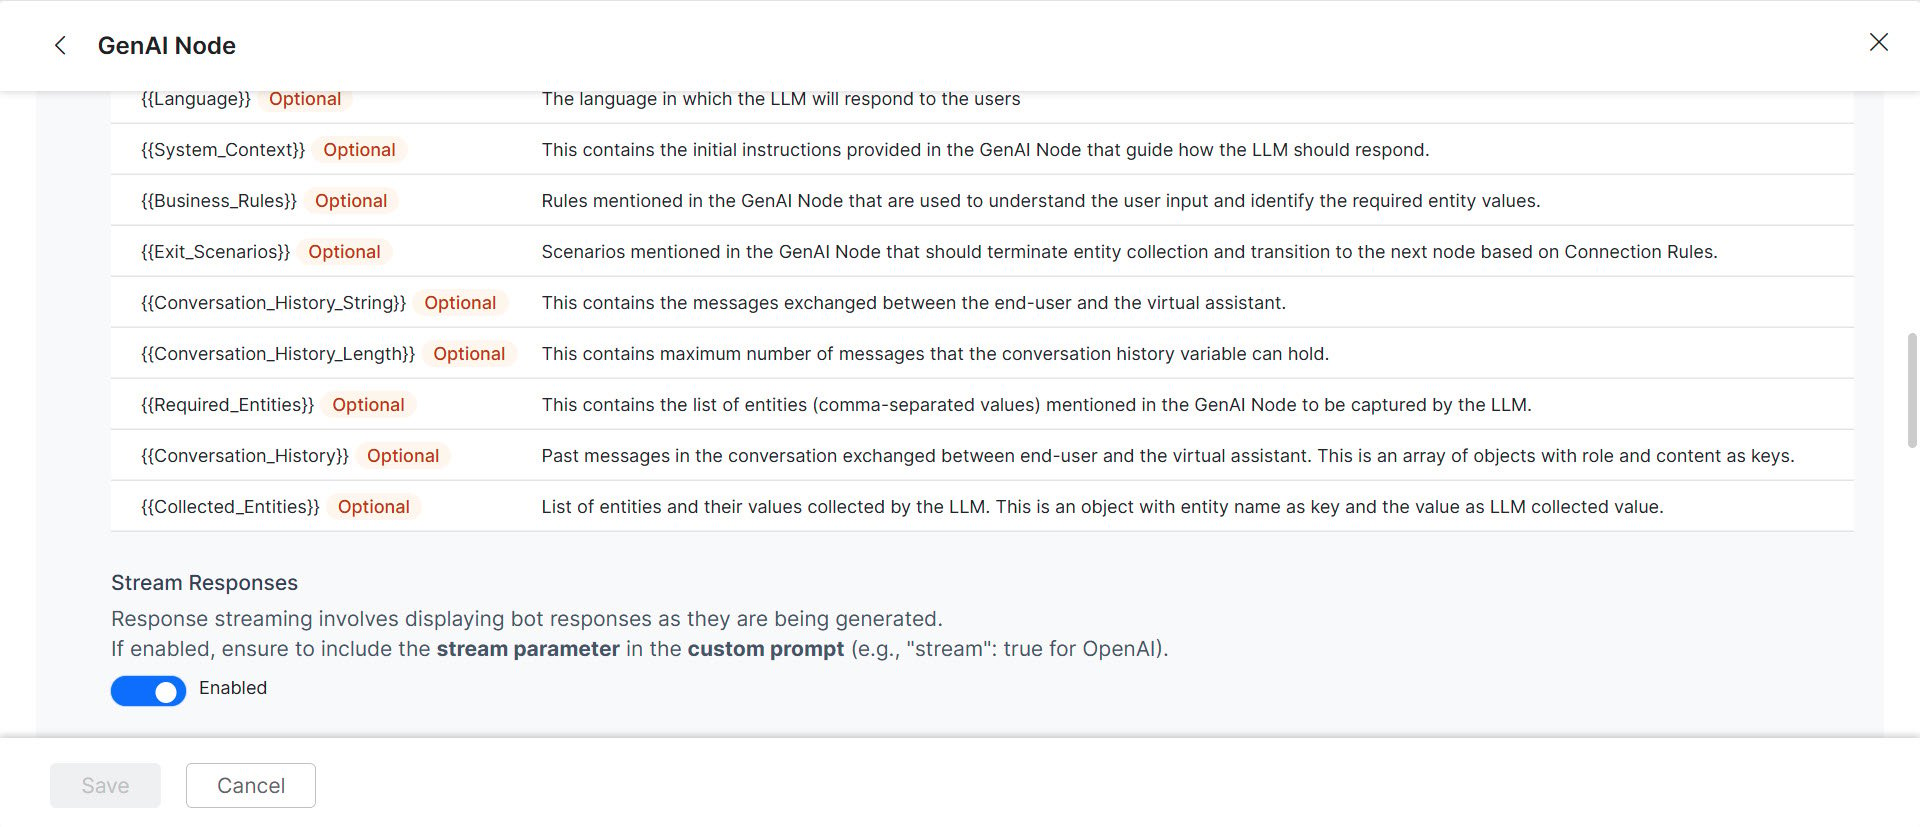
- Add
"stream": trueto the custom prompt when streaming is enabled. The saved prompt displays a “streaming” tag. - Enabling streaming disables the “Exit Scenario” field. Streaming applies only to Agent Node and Prompt Node features using OpenAI and Azure OpenAI models.
-
Fill in the Sample Context Values and click Test. If successful, the LLM response is displayed; otherwise an error appears. See Dynamic Variables

-
Map the response key: In the JSON response, double-click the key that holds the relevant information (for example,
content). The Platform generates a Response Path for that location. Click Save.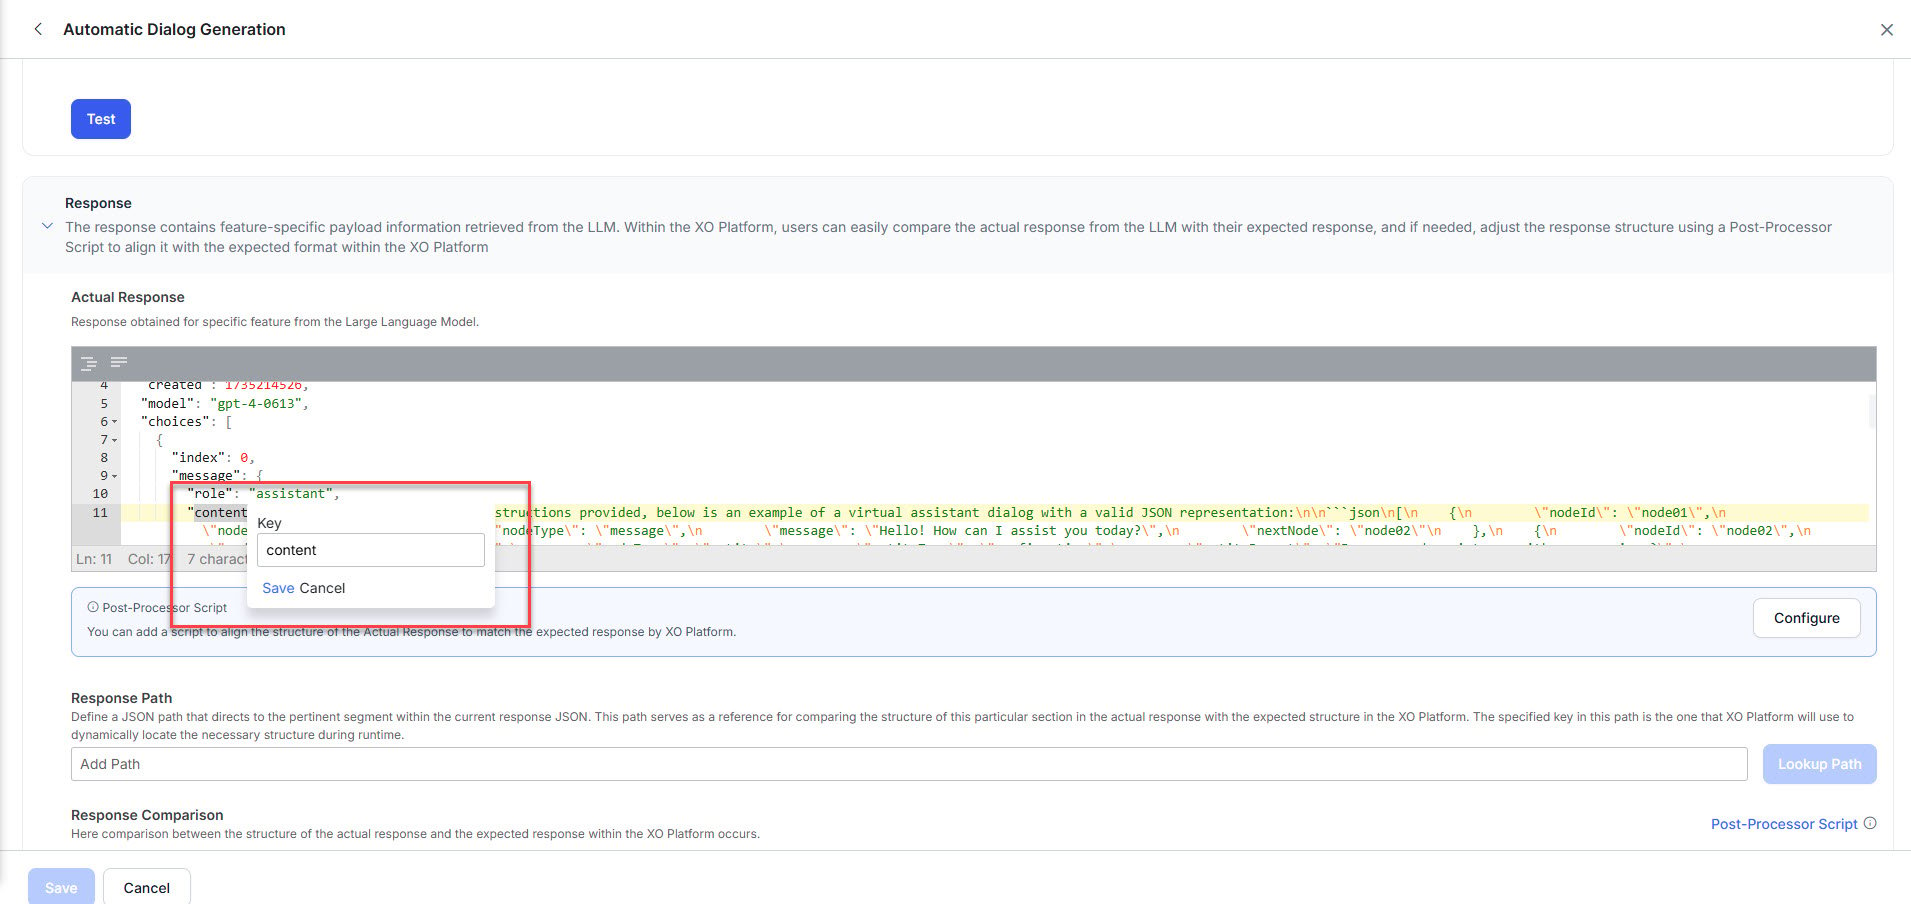
-
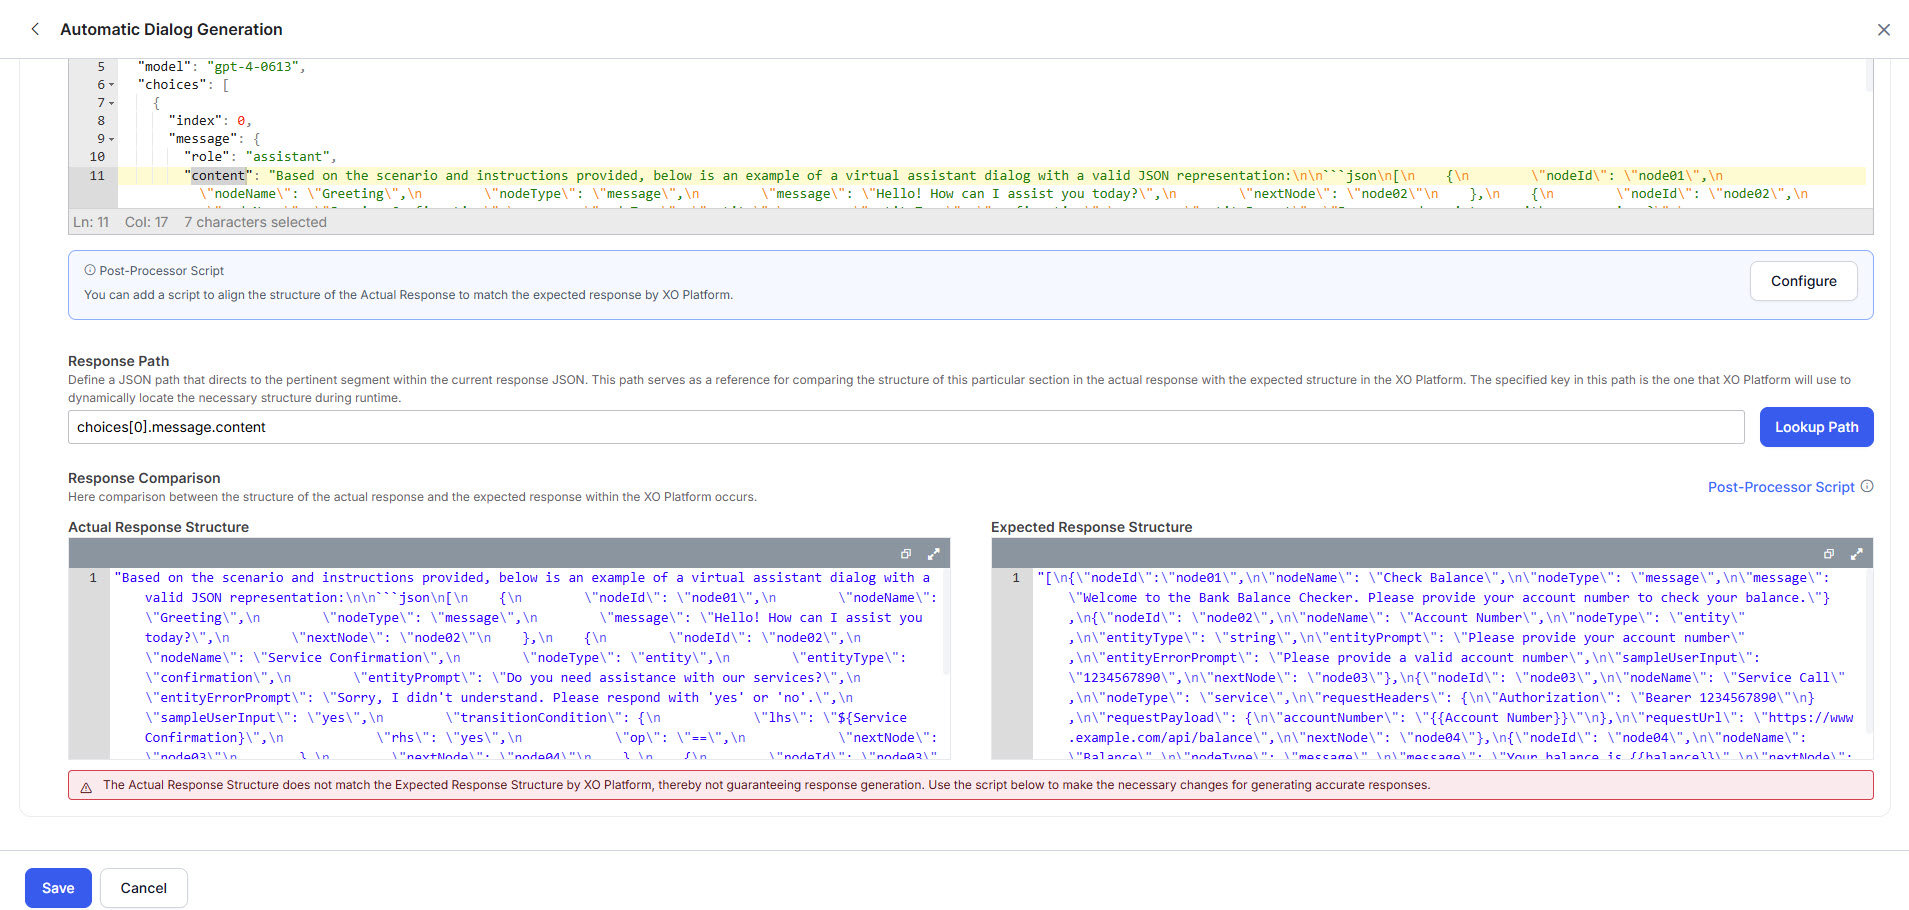
Click Lookup Path to validate the path.
-
Review the Actual Response and Expected Response:
-
Green (match): Click Save. Skip to step 12.

-
Red (mismatch): Click Configure to open the Post Processor Script editor.

-
Enter the Post Processor Script and click Save & Test.

-
Verify the result, then click Save. The responses turn green.

-
Enter the Post Processor Script and click Save & Test.
-
Green (match): Click Save. Skip to step 12.
-
(Optional) If Token Usage Limits are enabled for your custom model, map the token keys for accurate tracking:
- Request Tokens key:
usage.input_tokens - Response Tokens key:
usage.output_tokens
 Without this mapping, the Platform can’t calculate token consumption, which may lead to untracked usage and unexpected costs.
- Request Tokens key:
- Click Save. The prompt appears in the Prompts Library.